


By John Noctor, Chief Customer Success Officer
Nobody sets out to get AI wrong. That is the part most articles on this subject miss, and it is the reason so many of them read like a telling-off.
The failures I see on service desks are not the product of laziness or poor judgement. They are the product of eight or nine entirely reasonable decisions, taken in order, by people under pressure to show something workable by the end of the quarter. Each one is defensible on the day it is made.
A mistake is a one-off. A trap is a pattern. A pattern you can see coming is a pattern you can walk around.
So, here are eight AI traps I want to cover today:
1️⃣ You automated the cheap thirty per cent and called it done
2️⃣You are measuring deflection, not resolution
3️⃣ You built the AI people can see, not the AI that saves time
4️⃣ You expected AI to expose your knowledge gaps
5️⃣ You designed the handoff last
6️⃣ You adopted your vendor’s roadmap as your strategy
7️⃣ You left governance until after go-live
8️⃣ You have no baseline
I should be honest: I have been in the room for most of these, and on the wrong side of a couple of them.
#1 You automated the cheap thirty per cent and called it done
Password resets. Account unlocks. “Where has my ticket got to?” It is the obvious place to start, and for good reason. High volume, low complexity, and a result you can put on a slide.
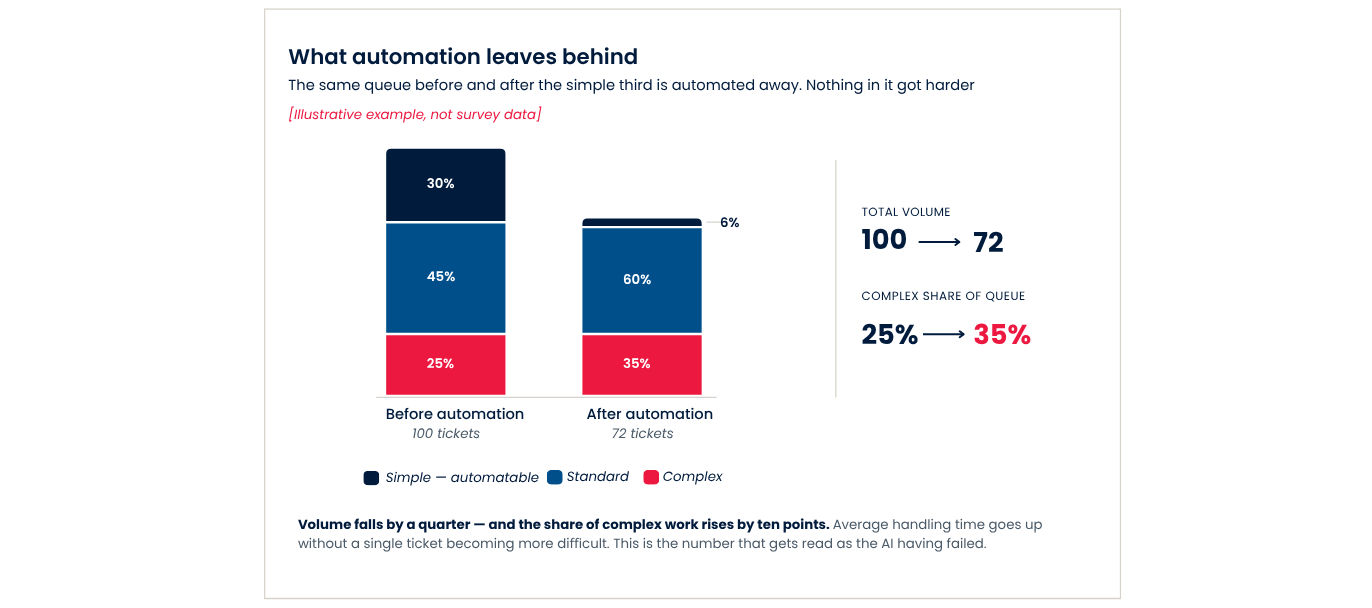
Those easy tickets were not only cheap. They were the recovery time between the hard ones. Take them out and every ticket your team touches is a difficult one. Handling time climbs. First-contact resolution slips. Six weeks in, the dashboard says the AI made things worse, and nobody can work out why.
It didn’t. Your average changed because your mix changed.
✅ The fix
Model the residual caseload before you deploy, not after. What is actually left when the easy third goes? Then adjust the targets, the shift pattern and the story you tell your board before the numbers move. Not while you are defending them.
#2 You are measuring deflection, not resolution
Deflection is the metric every vendor leads with, and it is the first one I would throw out.
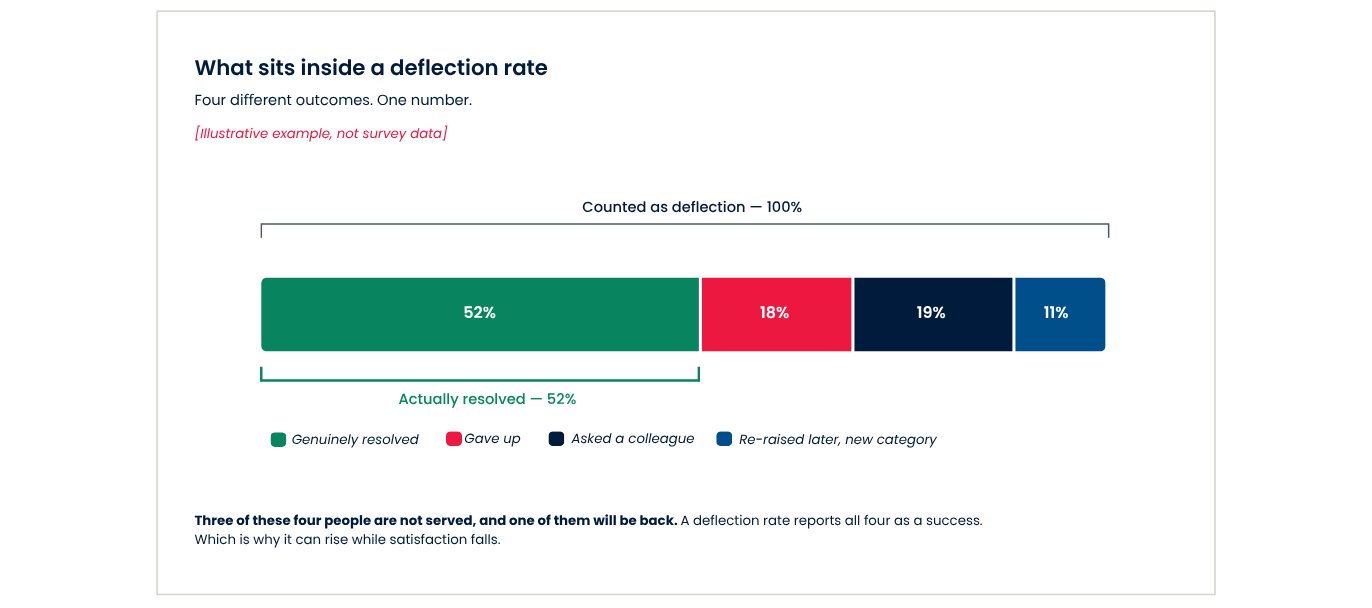
Deflection counts contacts that did not reach a human. It does not ask what became of the person. So, it counts the user who got a good answer and got on with their day. And it counts, identically, the user who gave up, the user who turned to the person sitting next to them, and the user who came back four days later and raised the same thing under a different category.
There is a worse problem underneath it. Deflection rewards a bot that is hard to escalate out of.
✅ The fix
Measure resolution without contact. One question: was this person’s issue actually dealt with, with no repeat contact on any channel within seven days? It will come out lower than your deflection rate. It will also be true.
#3 You built the AI people can see, not the AI that saves time
Ask a service desk where AI ought to go, and almost everyone points at the front door: a chat window, a virtual agent, something the user talks to.
But contact volume and analyst effort are not the same map.
Look at where the hours really go, and much of it sits behind the scenes. Reading a ticket to work out what it even is, categorising it, routing it to the right team, chasing the requester for the one field they left blank, writing the same update for the ninth time.
All of it is repetitive, high in volume and well suited to a machine.
✅ The fix
Start from a time study, not a channel report. Where does the hour go? Automate that. If the honest answer is that you do not know where the hour goes, that is the project, and it is cheaper than the one you were about to buy.
#4 You expected AI to expose your knowledge gaps
Everyone knows the rule: your AI is only as good as the knowledge behind it. So, desks audit the knowledge base, discover it is in worse shape than anyone had admitted, and press on with the AI project regardless, on the reasonable assumption that the gaps will surface in the results and can be fixed as they appear.
They will not surface. That is the trap.
A confident wrong answer looks exactly like a right one on every dashboard you own. A weak knowledge base does not fail loudly once you put AI on top of it. It fails quietly, at scale, and with better reporting than it had before.
✅ The fix
Sample for accuracy, not satisfaction. Pull fifty answers a week and have a human mark them right or wrong. And before go-live, measure what proportion of your actual demand is answerable from what you currently hold. If it is under half, you do not have an AI problem to solve yet.
And four more AI traps ( ⬇️Download the PDF for the full read)
#5 You designed the handoff last
“From the user’s side they have now told the story twice — the second time to someone who apparently was not listening the first time.”
#6 You adopted your vendor’s roadmap as your strategy.
“The question is not ‘what can it do now?’ It is ‘what do we need, and does this do it?'”
#7 You left governance until after go-live.
“Governance is the least interesting part of an AI project and the part most likely to stop it.”
#8 You have no baseline.
“This is the quiet one. It is also the one that costs you the argument.”
Each of these has a fix too, and none of them is technical. You’ll find them all in the full guide, together with the charts behind each trap and a one-page summary of all eight to share with your team.
➡️Download Eight AI Traps Every Service Desk Walks Into
Which of the eight is closest to home?
I will go first: number one. I have stood in front of a leadership team explaining why handling time went up after a successful automation — and I had not seen it coming.